
European AI Office Article 53 Compliance Templates: Foundation Model Copyright & Training Data Transparency
Global foundation model training datasets will face unprecedented public transparency as the European Union finalizes its binding Article 53 disclosure templates.
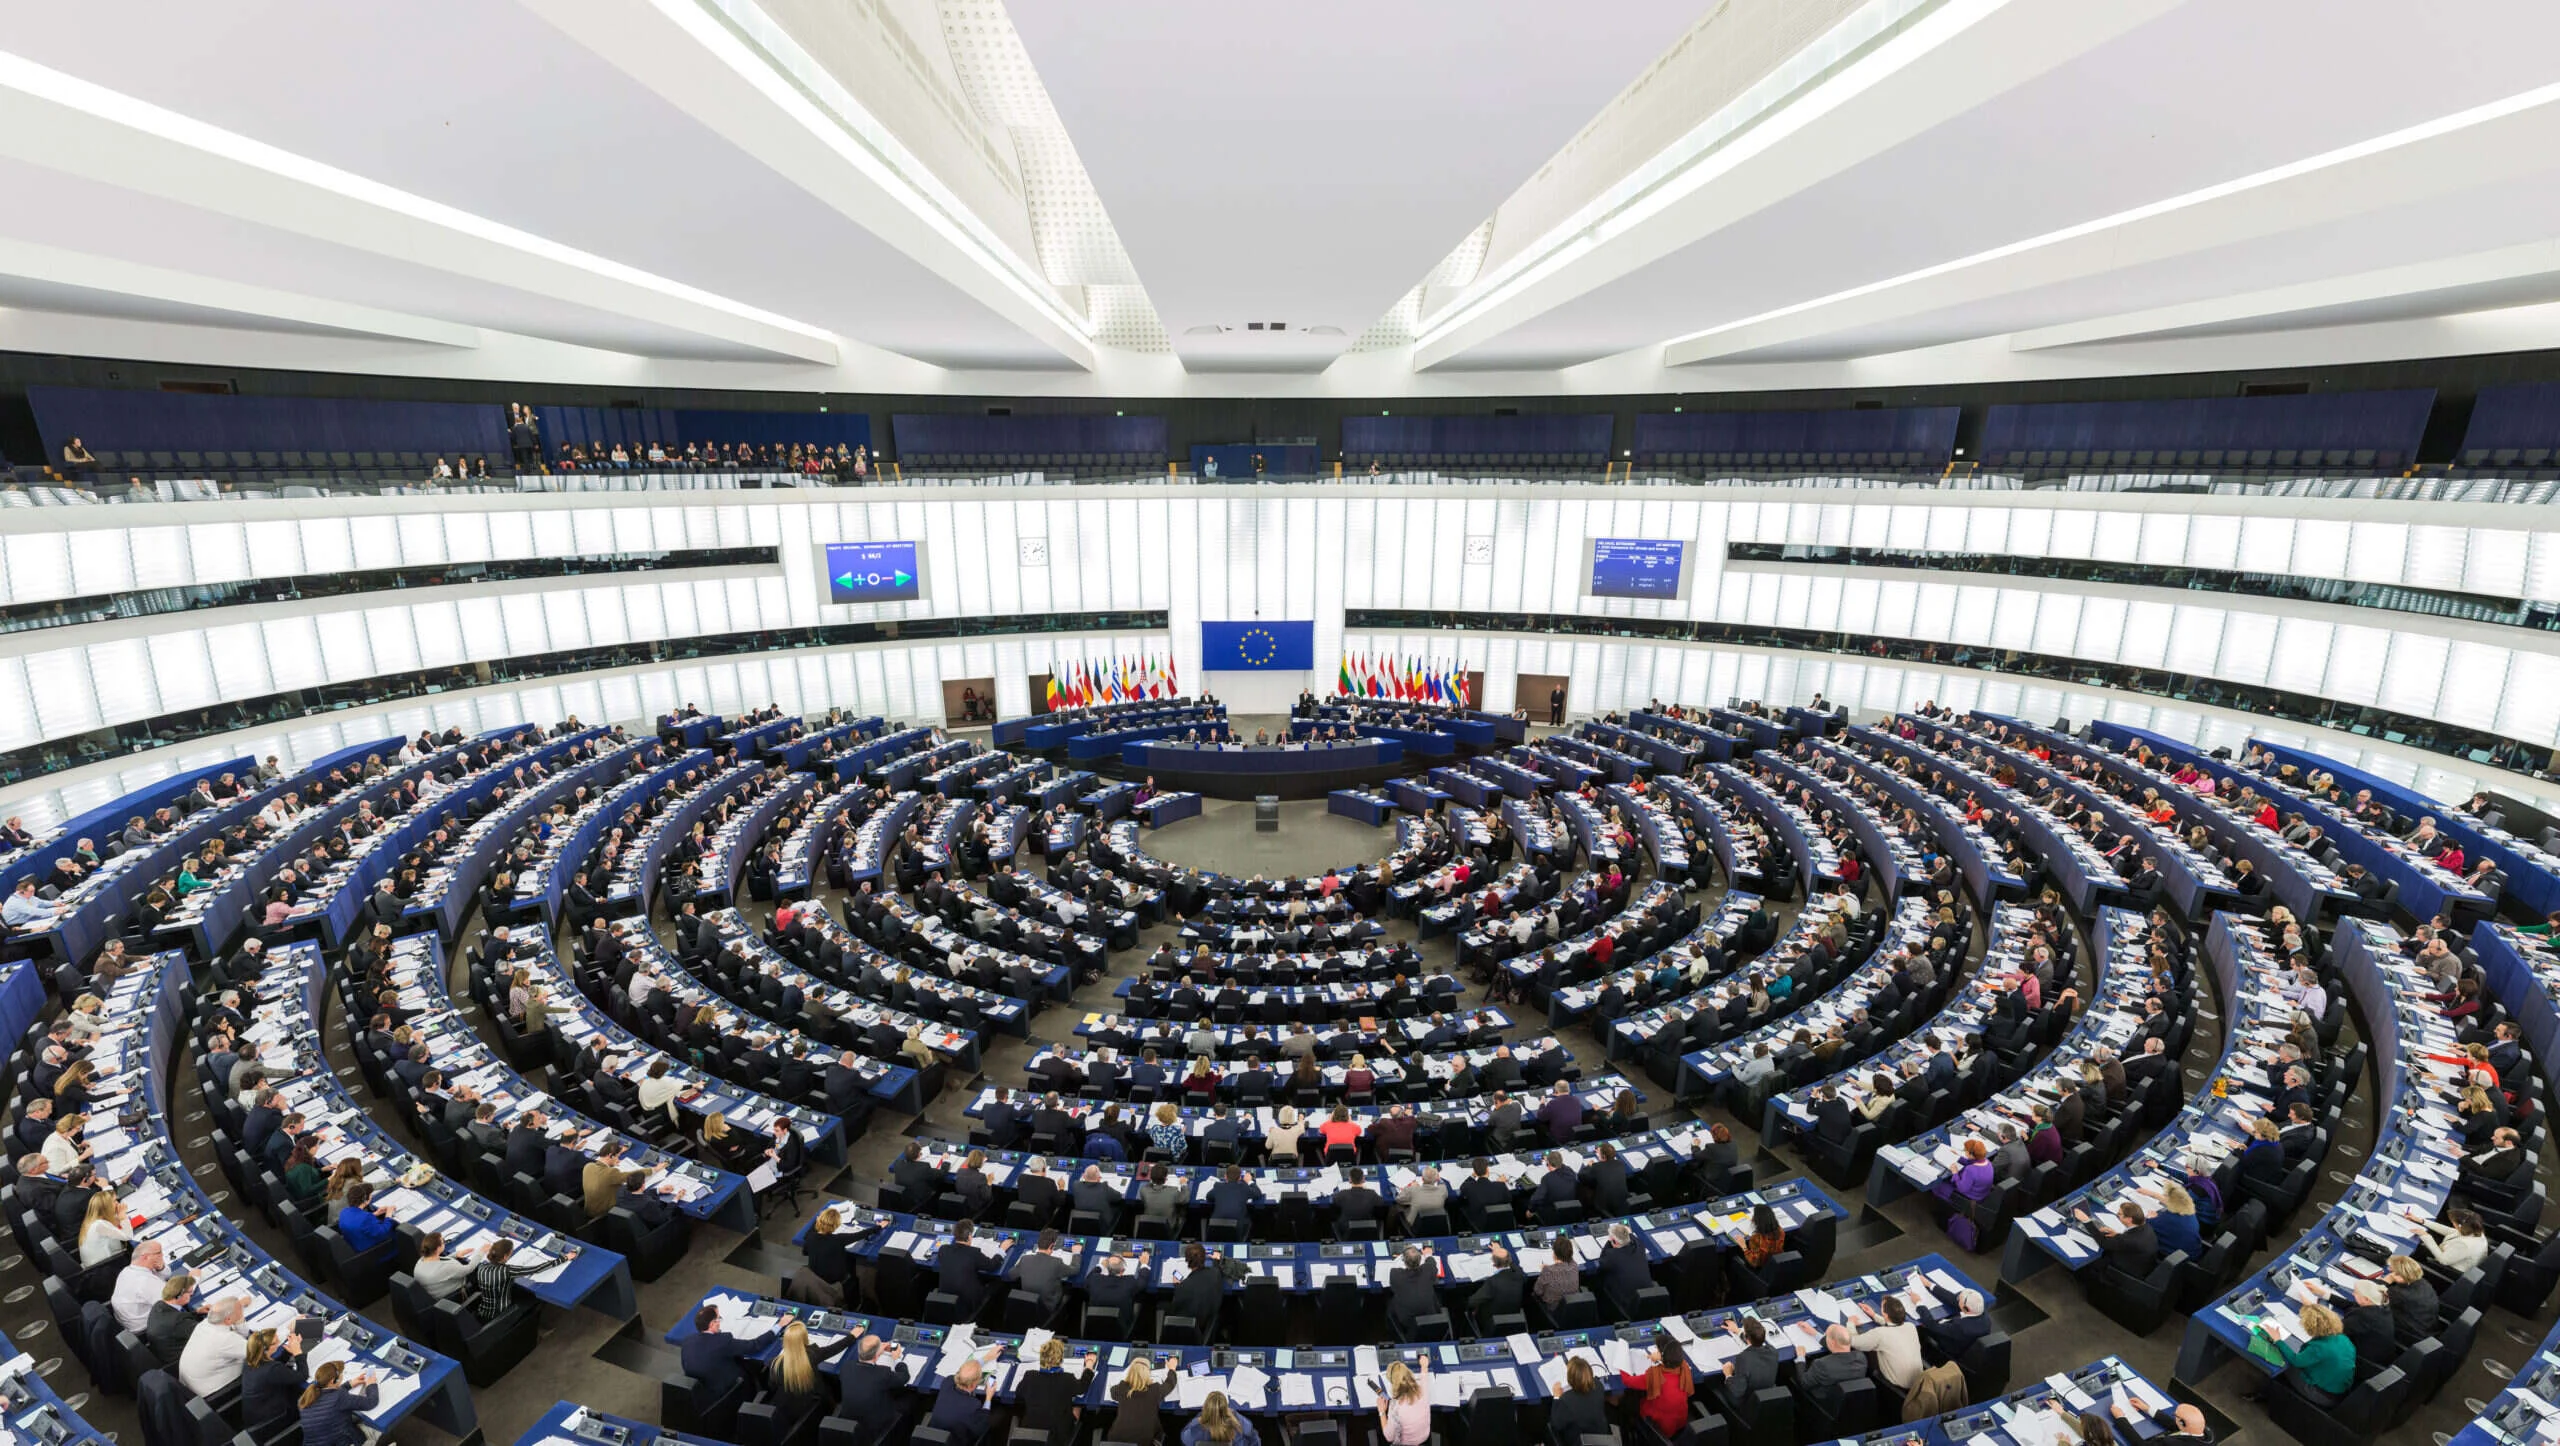
Demanding Transparency from the Black Box of Pretraining Data
For years, frontier artificial intelligence labs treated their training data recipes as closely guarded industrial secrets, citing commercial competitiveness. However, this lack of transparency triggered fierce pushback from copyright holders, authors, news publishers, visual artists, and music labels, who alleged that multi-trillion-token pretraining corpora unlawfully ingested copyrighted works without consent or remuneration.
Today in Brussels, the European AI Office, established under the European Commission to enforce the European Union Artificial Intelligence Act (EU AI Act), officially published the finalized compliance templates and guidelines for Article 53(1)(c) and (d). The rules establish legally binding disclosure obligations for all General-Purpose AI (GPAI) model providers operating in the European market.
1. The Comprehensive Training Data Summary Template
Under the finalized Article 53 template, model developers cannot simply state that their models were trained on “publicly available web data.” Providers must submit a structured, public technical filing detailing:
- Corpus Provenance & Taxonomy: High-level classification of all ingested datasets by domain (e.g., scientific literature, software code repositories, news articles, social media discussions, and encyclopedic knowledge).
- Copyright Opt-Out Compliance (TDM Exception): Explicit documentation proving that the crawler respected machine-readable opt-outs (including
robots.txt, TDM Reservation Protocol, and HTTP 402/403 header flags) in compliance with Article 4(3) of the EU Copyright Directive 2019/790. - Synthetic Data Proportions: The exact percentage and methodology used to generate synthetic training tokens, ensuring models do not obscure model collapse risks.
- Data Filtering & De-biasing Protocols: Measures implemented to scrub Personally Identifiable Information (PII) and illegal content (such as CSAM and violent extremism) prior to tokenization.
2. Enforcement Deadlines & Penalties
The European AI Office confirmed that the compliance templates will take full statutory effect in August 2026 for all newly released models, with a transition window extending to early 2027 for foundation models currently in commercial deployment. Failure to provide complete, truthful training disclosures carries administrative fines of up to €35 Million or 7% of total global annual turnover, whichever is higher.
EU AI Act Article 53 Compliance Requirements Summary
| Disclosure Section | Mandatory Documentation Requirements | Audit Standard | Target Beneficiaries |
|---|---|---|---|
| Web Scraping Methodology | Crawler architecture, user-agent strings, IP blocks | Automated log verification | Web publishers & digital media |
| Copyright Opt-Outs | Proof of honoring robots.txt & TDM headers | Independent technical audit | Authors, musicians & visual artists |
| Licensed Data Agreements | Commercial agreements with content publishers | Registry of licensed sources | Commercial partners |
| Synthetic Data Transparency | Percentage of tokens generated by AI teachers | Model card documentation | Researchers & downstream developers |
A New Global Benchmark for Open AI Development
Because multinational AI developers cannot easily partition their pretraining runs between Europe and the rest of the world without prohibitive infrastructure duplication, the EU’s Article 53 templates will inevitably create a “Brussels Effect”. Global developers—including OpenAI, Google, Meta, Anthropic, and Mistral—will be compelled to adopt rigorous, verifiable data provenance tracking across their worldwide training operations.